LLM Configuration
Device Agent uses the globally configured primary model to generate DeviceSpecs, understand chat requests, and call device commands. Configure a reachable model before the quick start; maintain each agent's prompt, time zone, and response preferences in Device Agent Configuration.
Console Configuration
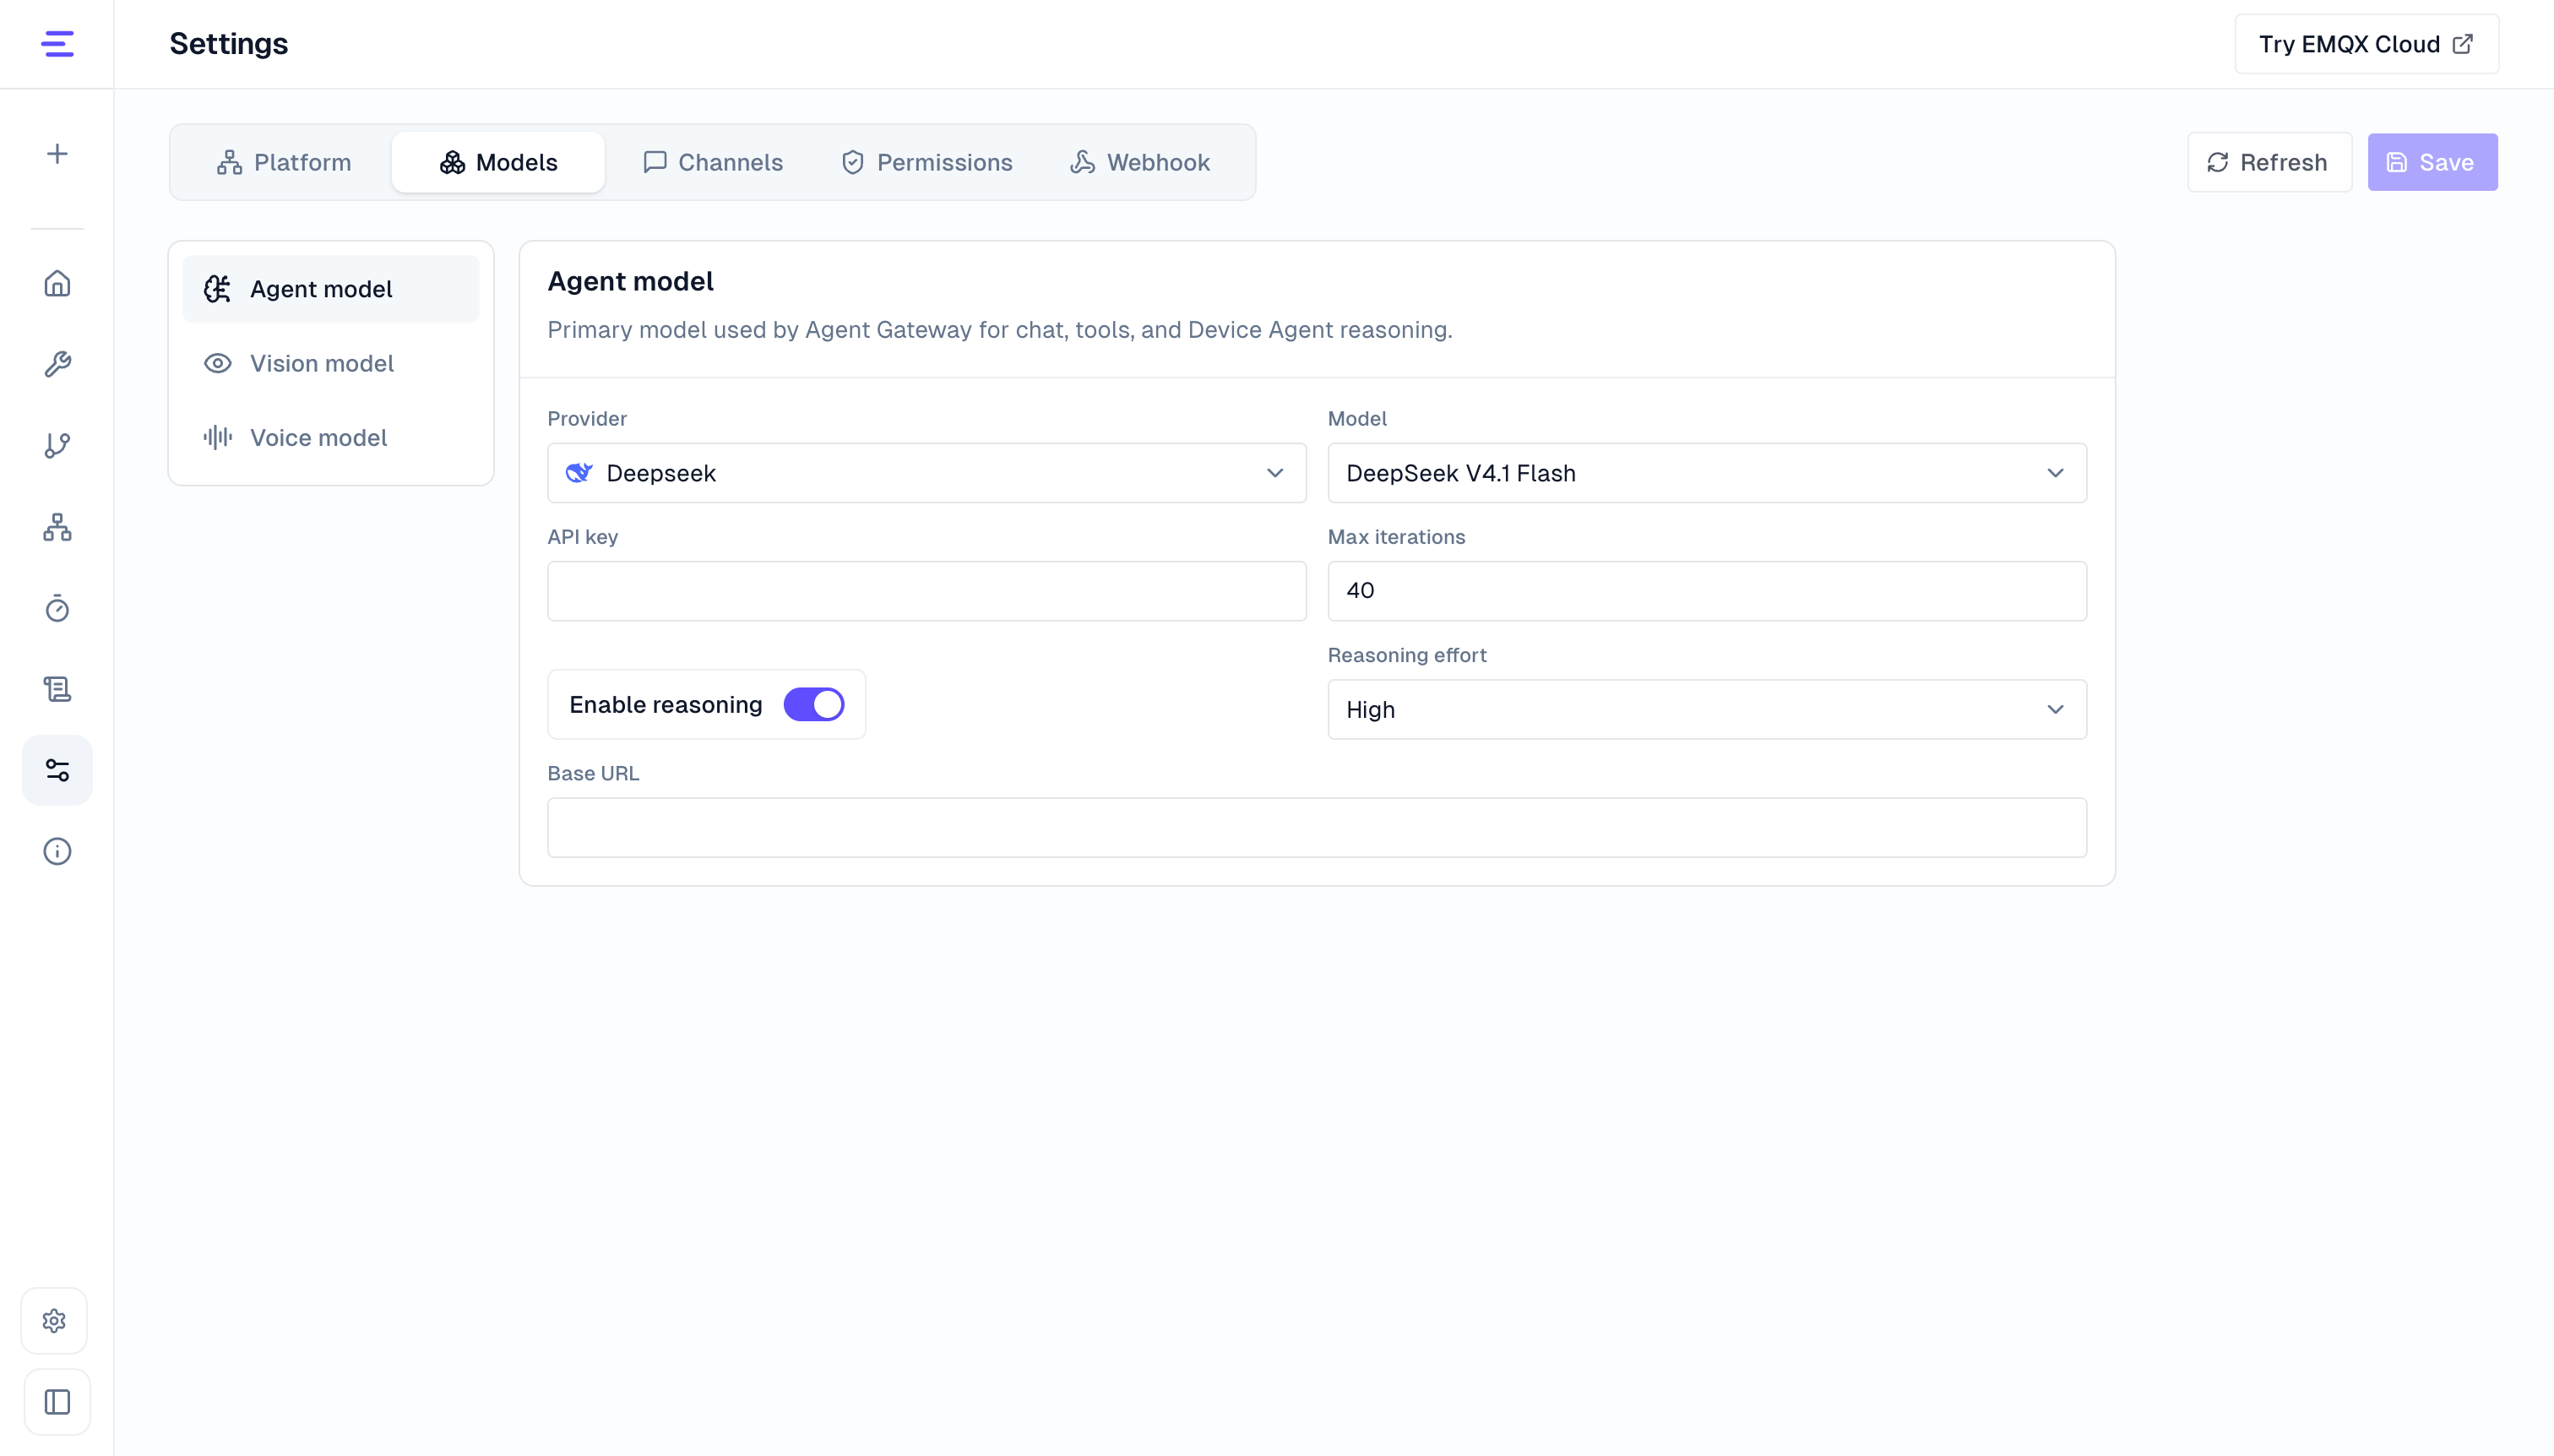
For a local installation, open http://127.0.0.1:3000. Platform users open the console address provided at delivery. Go to Settings → Models to view Agent model settings. Local installations can edit the fields below. Primary model settings are read-only in platform deployments; contact the deployment administrator to change them.
| Field | Notes |
|---|---|
| Provider | Select the LLM provider. Common entries include openai, anthropic, doubao, qwen, moonshotai-cn, ollama, and openai-compatible. |
| Model | Select or enter the model ID. Dropdown options come from the selected provider's available model list; custom entries such as openai-compatible allow manual model IDs. |
| API key | Enter the credential for the selected provider. |
| Base URL | Set this for custom OpenAI-compatible endpoints or local model services. openai-compatible usually requires it. ollama defaults to http://localhost:11434/v1 when left empty. |
| Max iterations | Maximum reasoning and tool-call iterations for one request. The default is usually enough. |
| Enable reasoning | Turn on the model's reasoning (thinking) capability. Off by default. Shown only when the selected model supports reasoning. View thinking content in chat when the model returns it. |
| Reasoning effort | Thinking effort while reasoning is enabled. The configuration supports minimal, low, medium (default), high, xhigh, and max. The page shows only levels supported by the selected model; models with an on/off switch only do not show this field. |
After saving, restart Agent Gateway before continuing if the page indicates that a restart is required.
Reasoning and Thinking Content
Enable Enable reasoning for complex analysis or requests that need several judgments. Higher effort can increase waiting time and model usage. Start with the default for routine queries and adjust based on the answers. Models that support only an on/off switch do not show an effort selector. After switching models, use the options offered by the new model.
When the model returns thinking content, chat displays a collapsible thinking area so you can follow its analysis progress. Use the final answer and tool results to confirm the request outcome.
LLM Providers
Available providers and models can change across versions and deployments. Use the list shown in Settings → Models as the source of truth.
Common configuration patterns:
| Type | Example LLM_PROVIDER | Configuration |
|---|---|---|
| OpenAI | openai | Set OPENAI_API_KEY. Fill Base URL only when using a proxy or custom compatible endpoint. |
| Anthropic | anthropic | Set ANTHROPIC_API_KEY. |
| Doubao / Volcengine Ark | doubao | Set DOUBAO_API_KEY or ARK_API_KEY. Defaults to https://ark.cn-beijing.volces.com/api/v3. The API key is not a Volcengine speech App ID or Access Key. |
| Other providers | google, deepseek, openrouter, xai, groq, mistral, and others | Select the provider and model in the console, then fill API key. For startup config, LLM_API_KEY can be used as the generic credential. |
| OpenAI-compatible endpoint | openai-compatible | Set a custom model ID, LLM_BASE_URL, and LLM_API_KEY. OPENAI_API_KEY can also provide the credential. |
| Qwen / DashScope | qwen | Set QWEN_API_KEY. Defaults to https://dashscope.aliyuncs.com/compatible-mode/v1. |
| Kimi | moonshotai-cn | Set KIMI_API_KEY. OPENAI_API_KEY can also be used as a compatible credential. Defaults to https://api.moonshot.cn/v1. |
| Kimi Coding | kimi-coding | Set KIMI_API_KEY. |
| Ollama | ollama | Local model service. Defaults to http://localhost:11434/v1 and usually does not need an API key. |
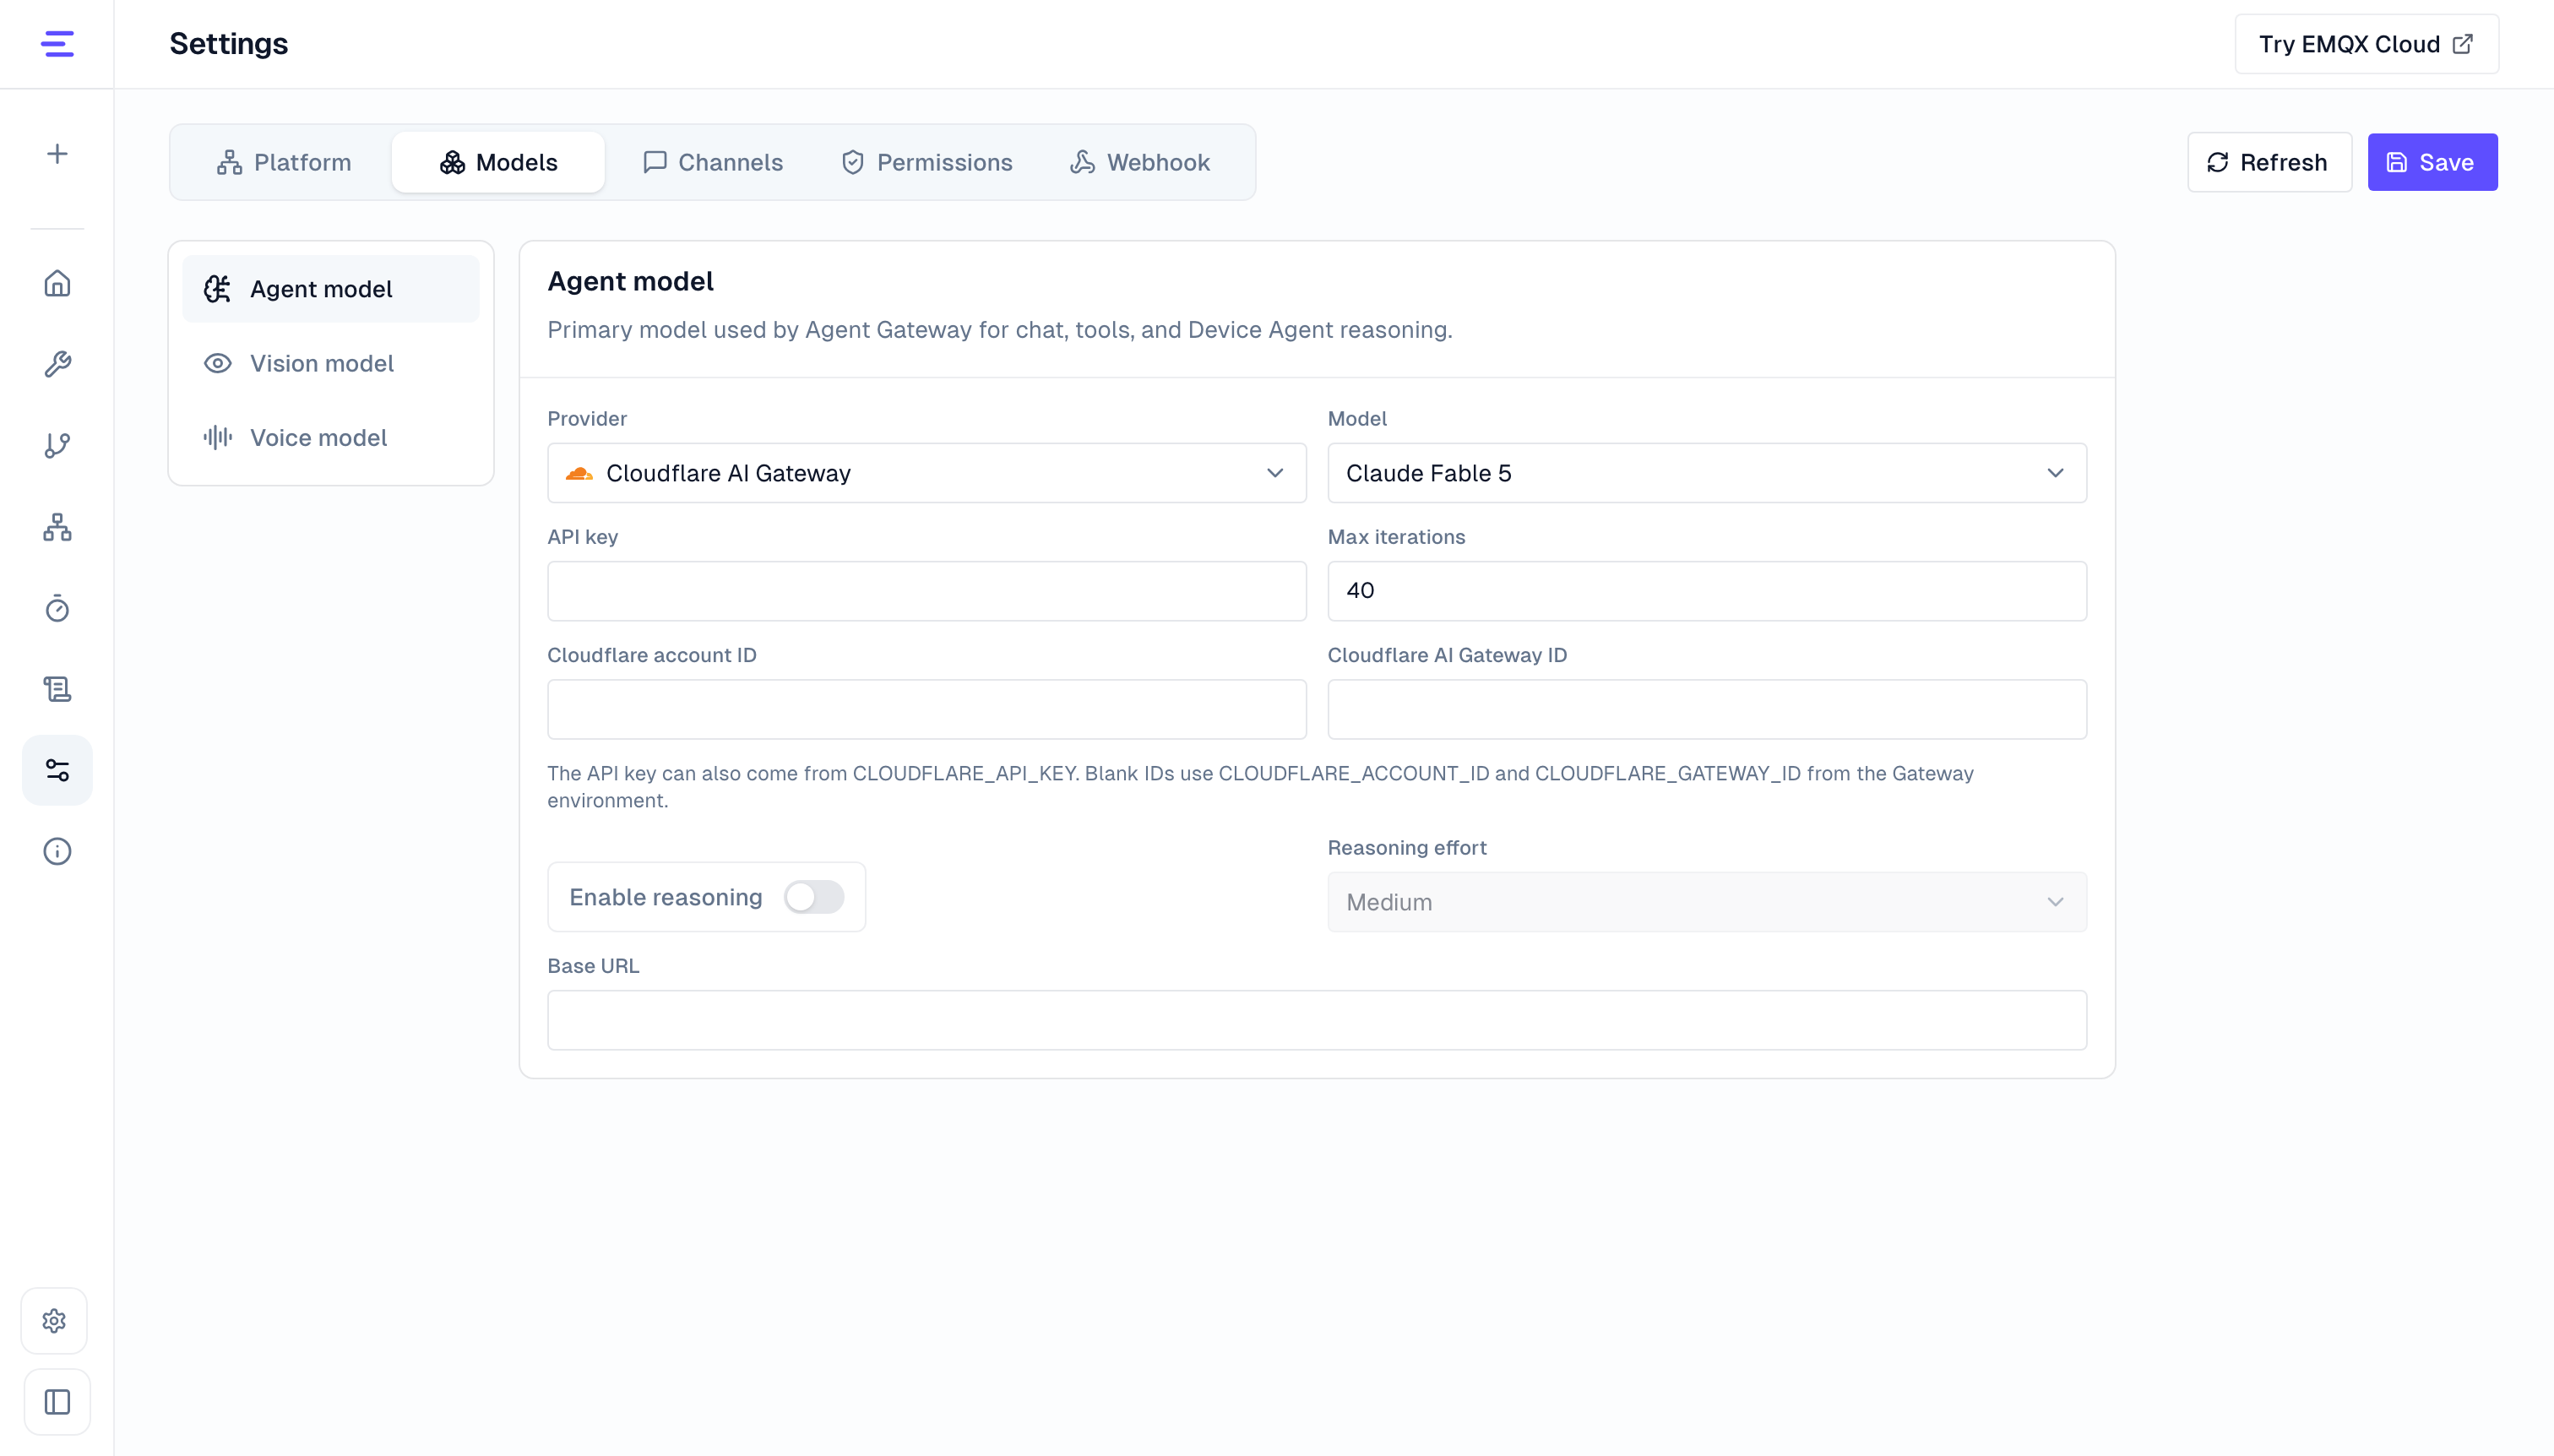
| Cloudflare Workers AI | cloudflare-workers-ai | Set Cloudflare Account ID and API key, then choose a model available to the account. |
| Cloudflare AI Gateway | cloudflare-ai-gateway | Set Cloudflare Account ID, Cloudflare AI Gateway ID, and API key. |
| Codex | openai-codex | Uses a special auth flow. See the Codex section below. |
Additional entries include:
- Google / Google Vertex (
google,google-vertex) - DeepSeek (
deepseek, including DeepSeek V4.1 Flash /deepseek-flash) - OpenRouter (
openrouter) - xAI (
xai) - Groq (
groq) - Mistral (
mistral) - Amazon Bedrock (
amazon-bedrock) - Azure OpenAI Responses (
azure-openai-responses) - Vercel AI Gateway (
vercel-ai-gateway) - GitHub Copilot (
github-copilot) - OpenCode (
opencode,opencode-go)
If an existing configuration uses provider kimi, change it to moonshotai-cn in the console or LLM_PROVIDER before use. Keep the model ID and API key unchanged. kimi-coding remains a separate provider.
Common examples are openai / gpt-5.5, anthropic / claude-sonnet-4-6, qwen / qwen-plus, deepseek / deepseek-flash, and ollama / llama3.2. Availability also depends on the provider account's permissions.
Cloudflare Model Services
For Cloudflare Workers AI, provide the Account ID and API key, then use a model available to the account. Cloudflare AI Gateway also needs the ID of an existing gateway.
The local console shows Cloudflare Account ID and Cloudflare AI Gateway ID for the corresponding providers. At startup, you can also set CLOUDFLARE_ACCOUNT_ID, CLOUDFLARE_GATEWAY_ID, and CLOUDFLARE_API_KEY; IDs left empty in the page can use these environment variables. Platform model services are configured by the deployment administrator.
Codex Auth
openai-codex is not configured like a normal OpenAI API key. The recommended path is to sign in with the Codex CLI on the machine running Device Agent, then let Device Agent read the default ~/.codex/auth.json. You can also override it with either of the following options:
LLM_PROVIDER=openai-codex
LLM_MODEL=<codex-model-id>
OPENAI_CODEX_AUTH_FILE=/path/to/auth.json
Or provide an access token directly:
LLM_PROVIDER=openai-codex
LLM_MODEL=<codex-model-id>
OPENAI_CODEX_ACCESS_TOKEN=...
When openai-codex is selected in the console, the regular API key field acts as a Codex access token override. The Codex auth file field points to auth.json. If neither field is set, Device Agent tries the Codex CLI default auth file.
If Codex CLI is already signed in and uses its default auth file, omit OPENAI_CODEX_AUTH_FILE. When set, this variable must use an absolute path; ~ is not expanded.
.env Configuration
Use .env for first startup, container deployment, or environments without UI access. Common examples are below.
OpenAI:
LLM_PROVIDER=openai
LLM_MODEL=gpt-5.5
OPENAI_API_KEY=sk-...
Qwen:
LLM_PROVIDER=qwen
LLM_MODEL=qwen-plus
QWEN_API_KEY=sk-...
Doubao on Volcengine Ark:
LLM_PROVIDER=doubao
LLM_MODEL=doubao-seed-2-1-pro-260628
DOUBAO_API_KEY=...
Use the Base URL field for another Ark region, such as https://ark.cn-shanghai.volces.com/api/v3, or a private gateway. A customer-specific Ark Model ID or Endpoint ID such as ep-... can be entered in Custom Ark Model ID or Endpoint ID. Models outside the built-in catalog default to text-only without reasoning because Device Agent cannot infer the capabilities behind a custom Model ID or Endpoint ID. A real Ark API key is always required, including when Base URL points to another region or a private gateway. Ark 401 and 403 responses include guidance to check the key and model permission. DOUBAO_API_KEY takes precedence over ARK_API_KEY, which takes precedence over LLM_API_KEY. VOLCENGINE_SPEECH_APP_ID and VOLCENGINE_SPEECH_ACCESS_KEY only authenticate ASR/TTS and cannot call Ark LLM APIs. Reasoning-capable catalog models expose an on/off reasoning switch; Device Agent does not show an unsupported effort selector.
OpenAI-compatible endpoint:
LLM_PROVIDER=openai-compatible
LLM_MODEL=your-model-id
LLM_BASE_URL=https://llm.example.com/v1
LLM_API_KEY=sk-...
Ollama:
LLM_PROVIDER=ollama
LLM_MODEL=llama3.2
LLM_BASE_URL=http://localhost:11434/v1
For Codex auth-file and access-token examples, see Codex Auth.
Local .env values override .device_agent/config.json at every startup. To retain console values, remove matching variables or keep both sources aligned; see Apply Behavior. Contact the deployment administrator to change platform providers, models, or credentials. See Deployment and Configuration.
Model Requirements
The quick start needs a model that can reliably generate structured output and perform tool calls. Use a model with tool-call support and at least an 8K context window. For longer device descriptions or conversations with more device state, use a 32K or larger context window.
Vision Model
See Vision Configuration for image input and separate vision services.