Voice Configuration
Device Agent uses the voice channel for speech recognition (ASR) and text-to-speech (TTS). Voice requests enter the selected device session; device online state, command execution, and reporting still use the selected IoT provider, MQTT, or the device SDK.
Console Configuration
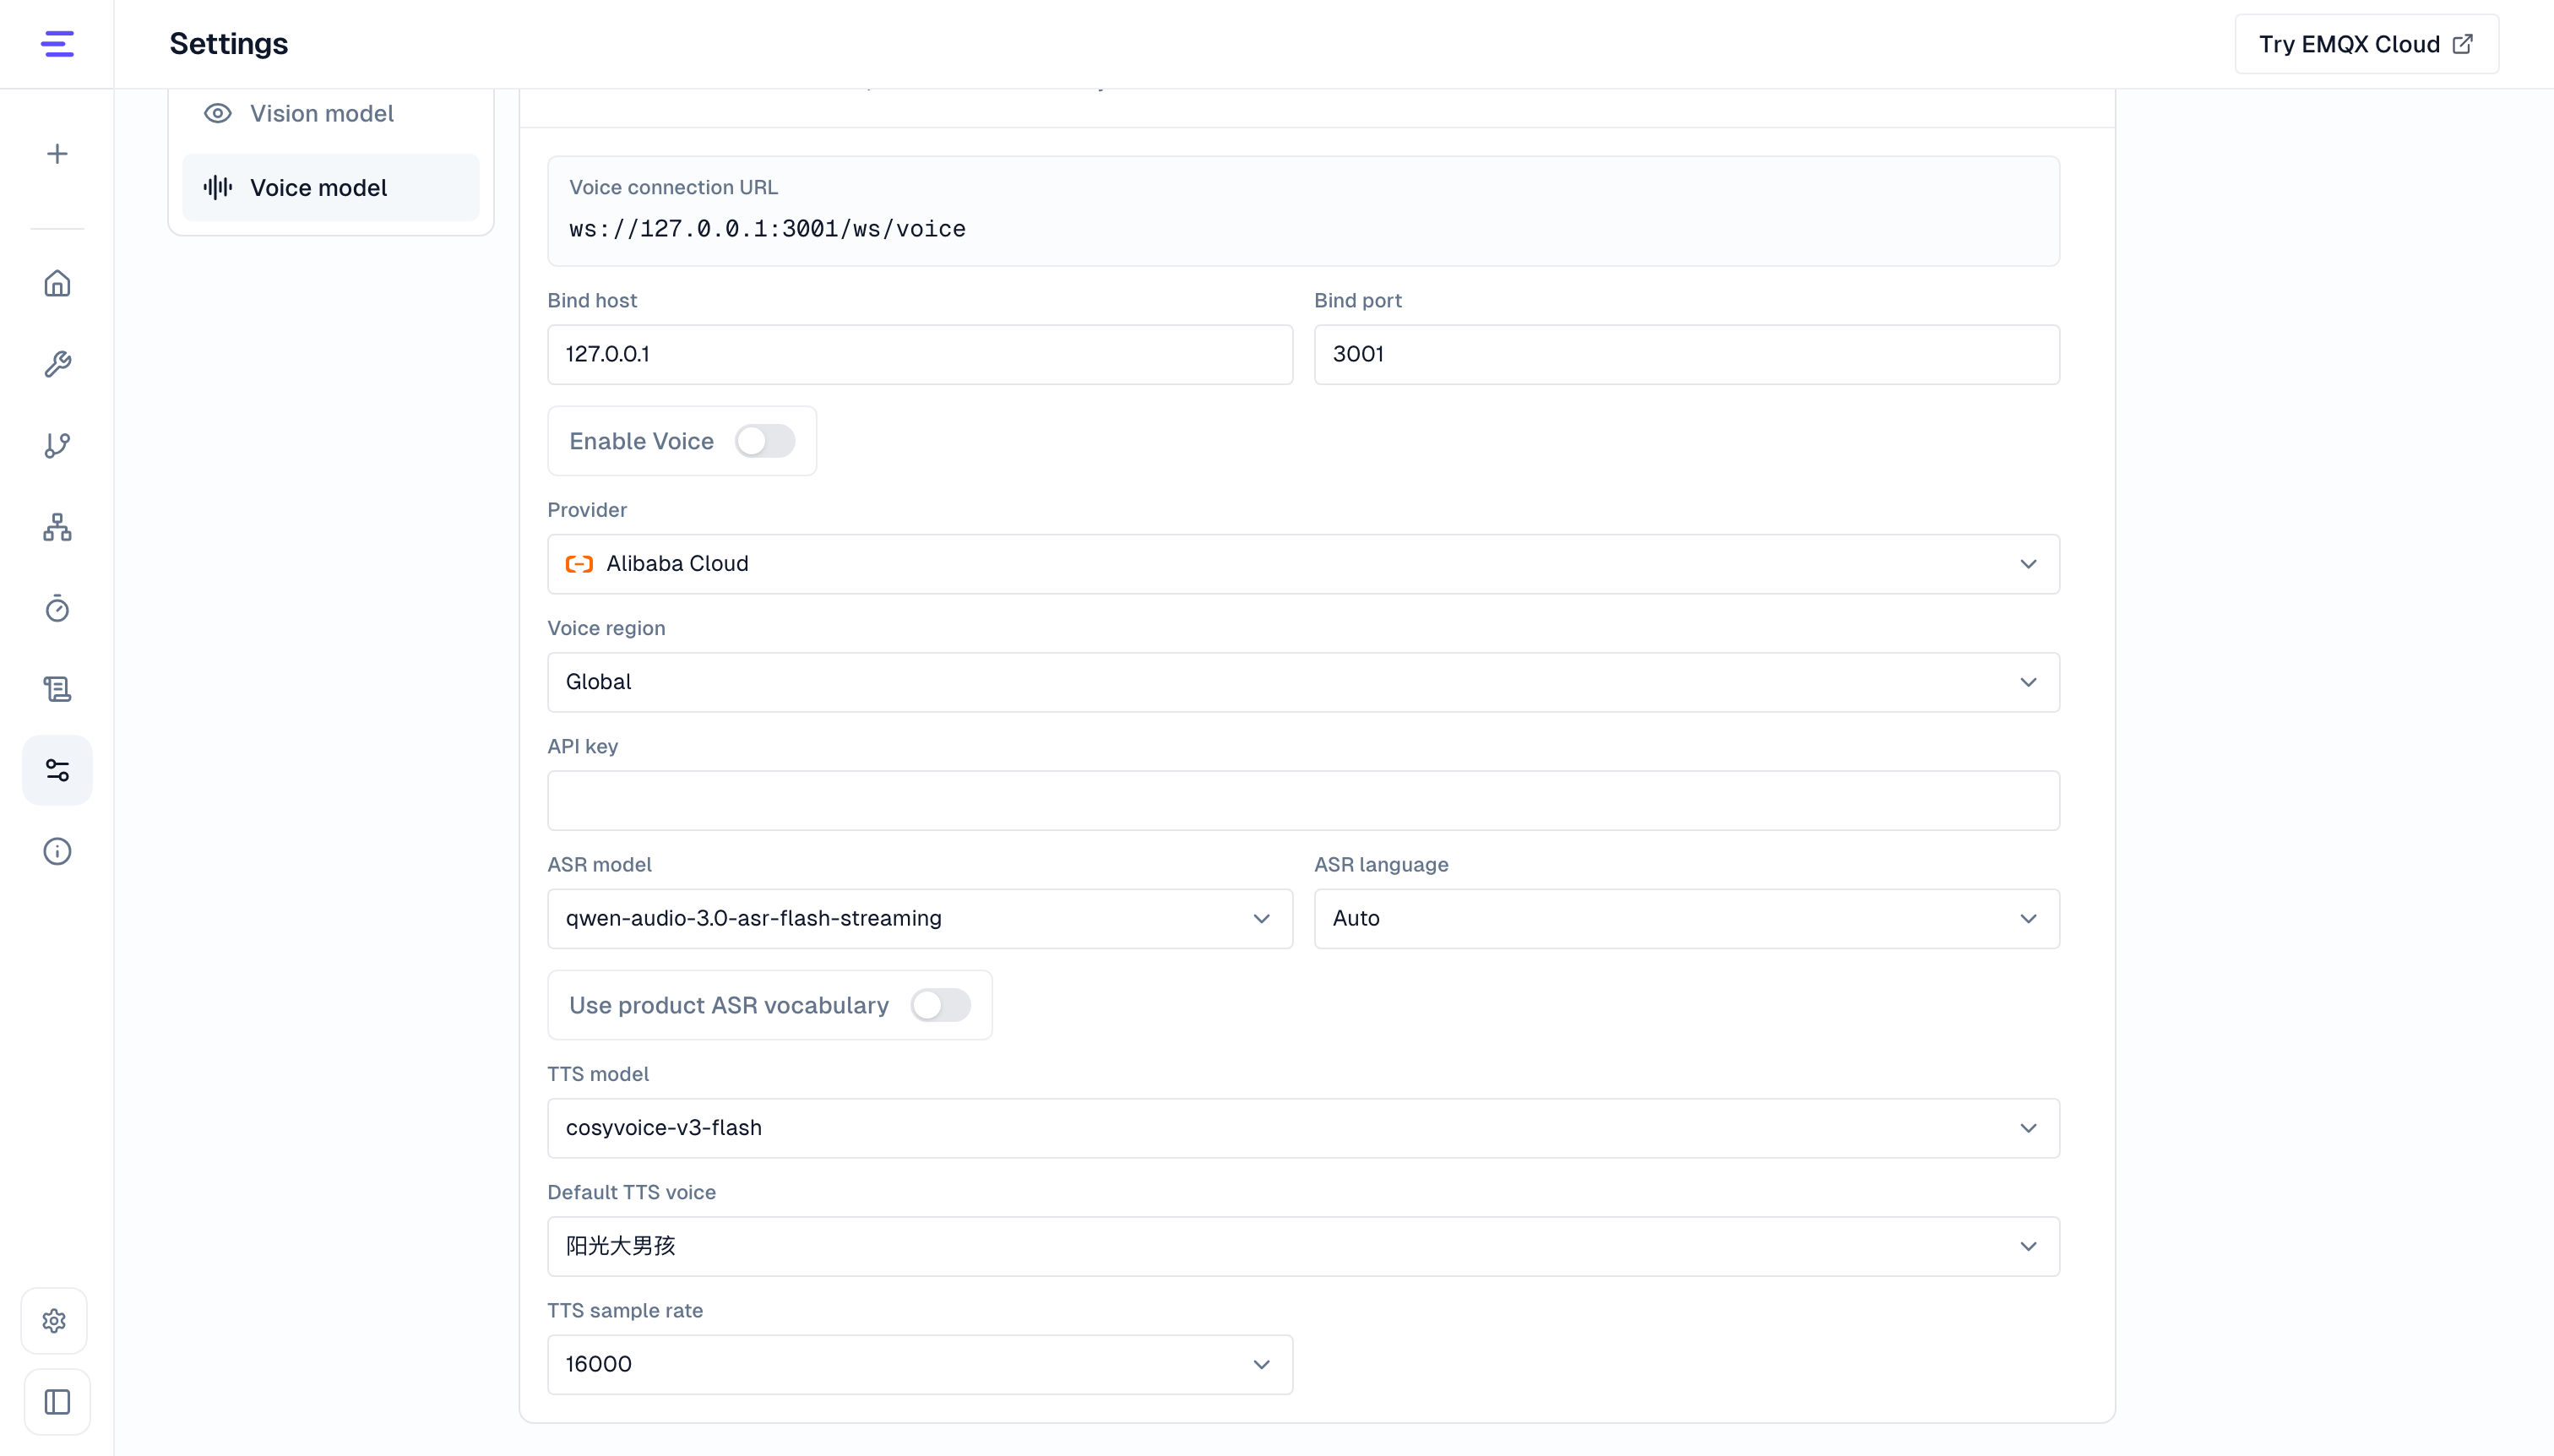
Open Settings → Models → Voice model. The local console defaults to http://127.0.0.1:3000; the platform uses its published console address.
| Field | Purpose |
|---|---|
| Voice enabled | Controls whether the /ws/voice channel is available. |
| Voice connection URL | Listener URL for direct local connections; the default is ws://127.0.0.1:3001/ws/voice. Platform clients use the public voice WebSocket URL published by the deployment administrator |
| Speech provider | Select volcengine, aliyun, aws, or elevenlabs. |
| Region | Supports cn, us, eu, and global; this affects eligible providers. |
| Speech recognition | ASR model, language, or resource ID. Fields vary by provider. |
| Use product ASR vocabulary | Let supported Aliyun recognition models use the current agent's hotwords |
| Text-to-speech | TTS model, voice, and sample rate. Fields vary by provider. |
| Provider credentials | Supply the selected service's credentials; platform deployments show their status, with changes managed by the deployment administrator |
Select a region and provider, configure recognition and synthesis, and save. Local provider, model, voice, and credential changes apply after saving. Enablement, bind address, port, or TLS changes require a restart. On the platform, follow the save and restart notice and obtain the public voice WebSocket URL from the deployment administrator. The listener URL shown on the page can differ from the published endpoint.
Aliyun Speech Recognition
After selecting Aliyun, choose one of these ASR models:
| Model | Agent hotword support |
|---|---|
qwen-audio-3.0-asr-flash-streaming | Supported; current default |
fun-asr-realtime | Supported |
fun-asr-realtime-2026-02-28 | Supported |
fun-asr-realtime-2025-11-07 | Supported |
fun-asr-realtime-2025-09-15 | Supported |
paraformer-realtime-v2 | Does not support the current vocabulary feature |
paraformer-realtime-v1 | Does not support the current vocabulary feature; use a 16 kHz recognition sample rate |
For models with automatic recognition, leave the recognition language empty to identify supported languages and Chinese dialects automatically. Model availability depends on the provider account and console options.
Use Agent Hotwords
For device names or business terms that are often misheard:
- Open the target agent card's More → Configuration overview → Speech recognition → Edit configuration and add hotwords and weights.
- Return to global voice settings and select an Aliyun ASR model with vocabulary support.
- Enable Use product ASR vocabulary and save.
- Start a new voice connection and inspect recognized text from a sentence containing a hotword.
Vocabulary belongs to the current agent, so agents sharing a global speech service can maintain different hotwords. The switch is unavailable for models without vocabulary support. See Device Agent Configuration for hotword editing and weights.
Aliyun Synthesis and Voices
The TTS model selector currently provides:
| Family | Models |
|---|---|
| CosyVoice | cosyvoice-v3-flash, cosyvoice-v3-plus, cosyvoice-v2 |
| Qwen Audio | qwen-audio-3.0-tts-flash, qwen-audio-3.0-tts-plus |
Select a model first, then choose a voice from its list. System voices differ between models. After switching models, check that the selected voice meets your needs; the interface selects an available voice when the previous one is incompatible.
Save and make a short voice request to check the actual sound and playback speed. Custom voices also require the appropriate provider-account permissions.
Agent Voice Experience
Global settings provide recognition, synthesis, and connections. Maintain an agent's hotwords, voice tool scope, identity replies, waiting messages, question matching, audio reuse, and timeout replies in Device Agent Configuration.
For example, provide a short acknowledgement while waiting for a query, and use configured matching to select feedback for repeated questions. Voice scope determines available tools; A2A bindings determine collaboration targets. Waiting feedback does not grant additional tool permissions or device capabilities.
See Voice Interaction for use and verification. Platform deployments can use Monitoring to inspect voice outcomes, latency, and usage.
Speech Providers
| Provider | Regions | Main settings |
|---|---|---|
Volcengine (volcengine) | cn, global | VOLCENGINE_SPEECH_APP_ID, VOLCENGINE_SPEECH_ACCESS_KEY, plus ASR/TTS resource IDs, language, voice, and sample rate. |
Aliyun DashScope (aliyun) | cn, global | ALIYUN_DASHSCOPE_API_KEY or QWEN_API_KEY, plus ASR model, TTS model, voice, and sample rate. |
AWS (aws) | us, eu, global | AWS_ACCESS_KEY_ID, AWS_SECRET_ACCESS_KEY, AWS_REGION, plus Transcribe language and Polly voice. |
ElevenLabs (elevenlabs) | us, eu, global | ELEVENLABS_API_KEY, API endpoint, ASR model, TTS model, voice, and sample rate. |
VOICE_REGION=cn uses Volcengine or Aliyun; us uses AWS or ElevenLabs; eu requires an AWS eu-* region or the ElevenLabs EU residency endpoint; global does not restrict providers.
Platform choices depend on configured provider credentials.
.env Configuration
Use .env for first startup, containers, or environments without UI access. Matching local variables override console values at each startup; the deployment administrator maintains platform credentials. See Apply Behavior.
Aliyun DashScope:
VOICE_ENABLED=true
VOICE_REGION=cn
ALIYUN_DASHSCOPE_API_KEY=sk-...
ALIYUN_ASR_MODEL=qwen-audio-3.0-asr-flash-streaming
ALIYUN_ASR_VOCABULARY_ENABLED=false
ALIYUN_TTS_MODEL=cosyvoice-v3-flash
ALIYUN_TTS_VOICE=longanyang
To use agent hotwords, confirm model support and set ALIYUN_ASR_VOCABULARY_ENABLED=true.
Volcengine:
VOICE_ENABLED=true
VOICE_REGION=cn
VOLCENGINE_SPEECH_APP_ID=...
VOLCENGINE_SPEECH_ACCESS_KEY=...
VOLCENGINE_TTS_VOICE=zh_female_shuangkuaisisi_moon_bigtts
AWS:
VOICE_ENABLED=true
VOICE_REGION=us
AWS_ACCESS_KEY_ID=...
AWS_SECRET_ACCESS_KEY=...
AWS_REGION=us-east-1
AWS_TRANSCRIBE_LANGUAGE_CODE=en-US
AWS_POLLY_VOICE=Joanna
ElevenLabs:
VOICE_ENABLED=true
VOICE_REGION=us
ELEVENLABS_API_KEY=...
ELEVENLABS_TTS_MODEL_ID=eleven_multilingual_v2
ELEVENLABS_TTS_VOICE=UgBBYS2sOqTuMpoF3BR0
See Environment Variables for the full reference.
Bind Address and TLS
The local voice service defaults to 127.0.0.1:3001. For LAN or server clients, set a reachable bind address and restart:
VOICE_HOST=0.0.0.0
VOICE_PORT=3001
For direct local connections, allow network access to the port, then copy the connection URL from Settings → Models → Voice model. Confirm that its host and port are reachable from the client.
An HTTPS console requires a wss:// voice connection. To enable TLS on the local voice listener:
VOICE_TLS_ENABLED=true
VOICE_TLS_CERT_FILE=/path/to/cert.pem
VOICE_TLS_KEY_FILE=/path/to/key.pem
For platform or reverse-proxy access, use the deployment administrator's published voice WebSocket URL with its public host, port, and /ws/voice path. This address can differ from the console address. An HTTPS console uses wss://; TLS can terminate at the proxy, whose external port can differ from the voice listener's port.
Remote clients follow the deployment's login or device-identity connection method; see Platform Deployment. Protocol and device connection parameters are in API Reference.