Data Collection, Processing and Forwarding
This section is the configuration manual for real projects: connecting real devices, scaling up, and running reliably over time. To get one pipeline working in fifteen minutes with a simulator instead, see the Quick Start.
Configuration flow
| Step | What to do | Key point |
|---|---|---|
| 1 | Create a southbound driver | Pick the driver for the device protocol and fill in connection parameters. Per-protocol parameters, data types, and address formats are in Southbound Drivers |
| 2 | Groups and tags | Settle the grouping strategy first — the group is the unit of collection, reporting, and subscription, so it determines payload shape and bandwidth |
| 3 | Data monitoring and device control | Confirm tags are collecting, and write back to devices from here |
| 4 | Processing data before forwarding (optional) | Use the rules engine to filter, convert, aggregate, or rename fields — particularly worthwhile at high volume or when the polling rate exceeds what the business needs |
| 5 | Create a northbound application | Choose where the data goes; for selection guidance see Northbound Applications |
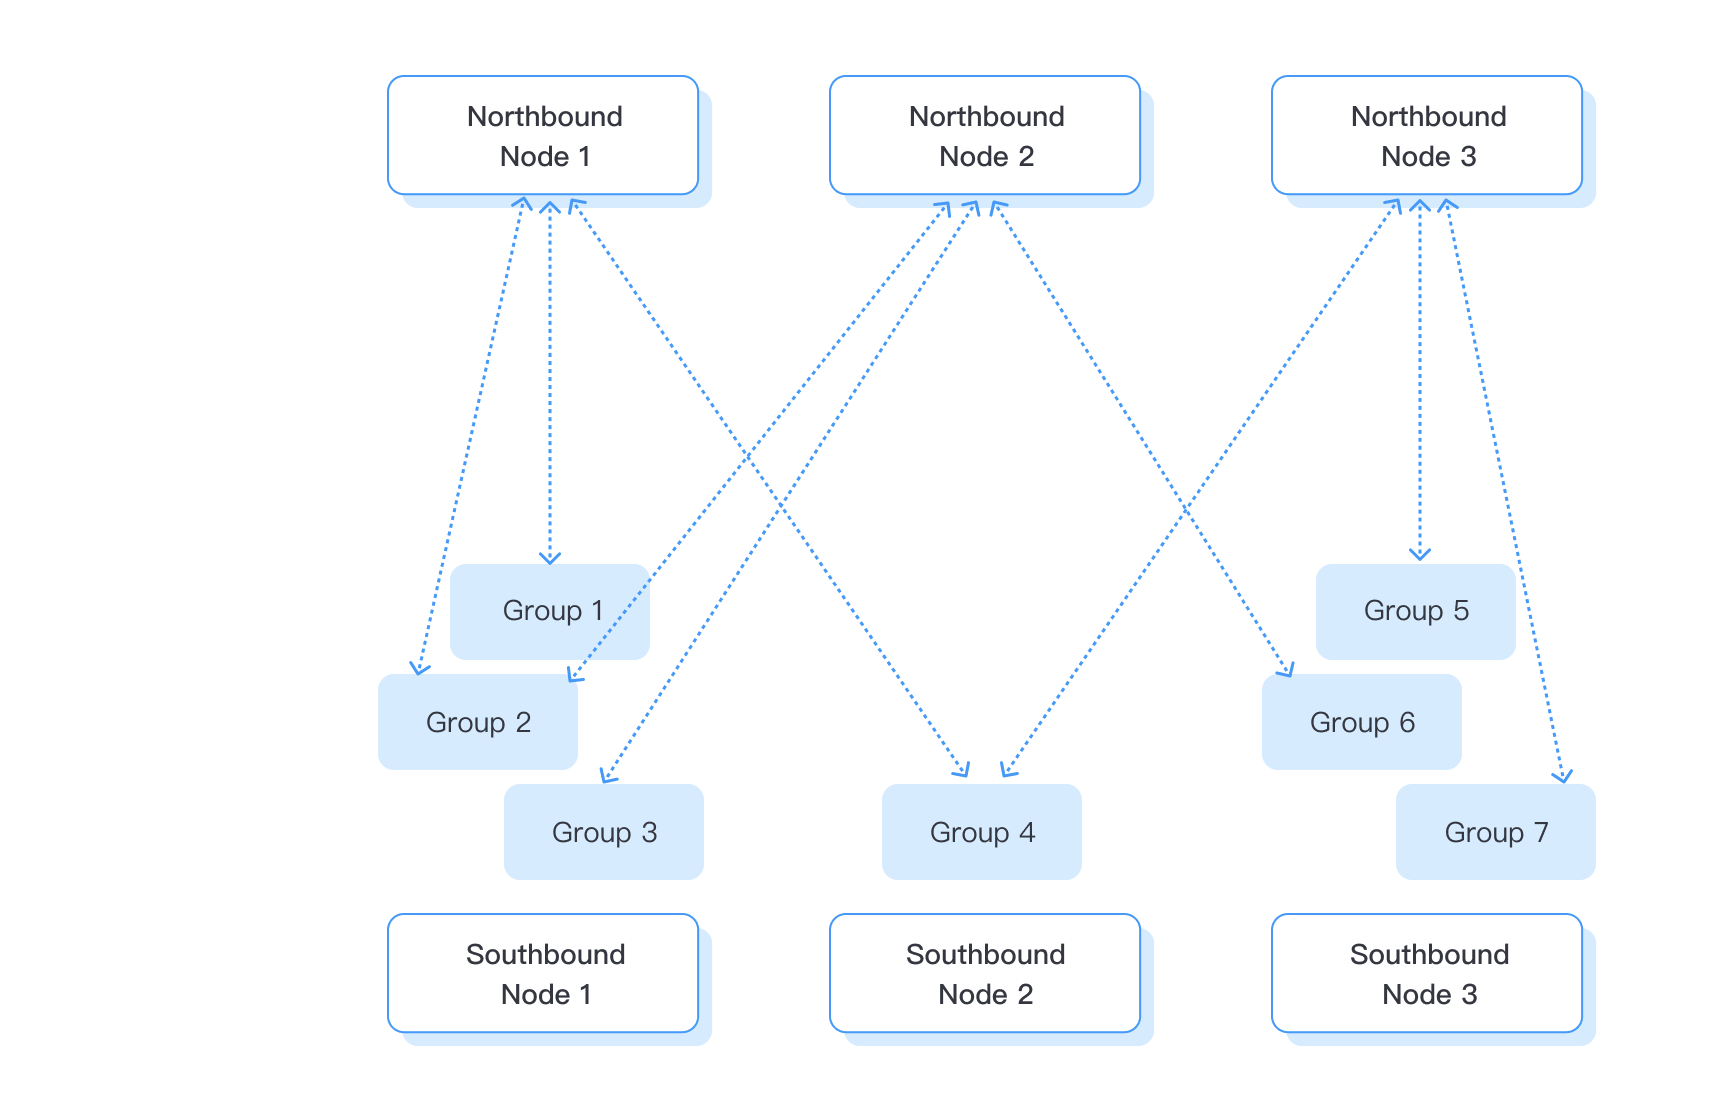
| 6 | Subscribe to southbound data | Attach collection groups to the application and data starts flowing |
Repeat steps 1 and 2 until every device is configured. Repeat steps 5 and 6 to send the same data to several destinations.
Step 4 is optional: data can be published as collected or processed by a rule first, and both can run at once. For the criteria, see Processing Data Before Forwarding; for the full capability of the rules engine — sources, SQL, windows, and sinks — see the separate Data Processing section.
For many devices, large tag counts, or a migration from KEPServerEX or Litmus Edge, see Bulk Configuration and Migration.
The overall process is shown below:
TIP
To filter, convert, or aggregate before forwarding, see Data Processing. For how nodes, groups, and tags relate, see Architecture · Core data model.
Configuration specification
Confirm the per-instance limits during project design:
| Object | Limit |
|---|---|
| Node name length | 128 characters |
| Tag name length | 128 characters |
| Tag address length | 128 characters |
| Tag description length | 256 characters |
| Group name length | 128 characters |
| Groups per southbound driver | 512 |
| Groups subscribed per northbound application | Unlimited |
| Driver or application module name length | 32 characters |
| Driver or application file name length | 64 characters |
| Driver or application description length | 512 characters |
| Southbound polling interval | 100 ms minimum |
There is no hard limit on total tag count; it depends on the CPU and memory available. For measured figures, see Performance. With adequate hardware, keep a single instance under 100,000 tags and 100 southbound drivers; beyond that, split the workload across several EMQX Neuron instances. See Hardware requirements.