Data Processing
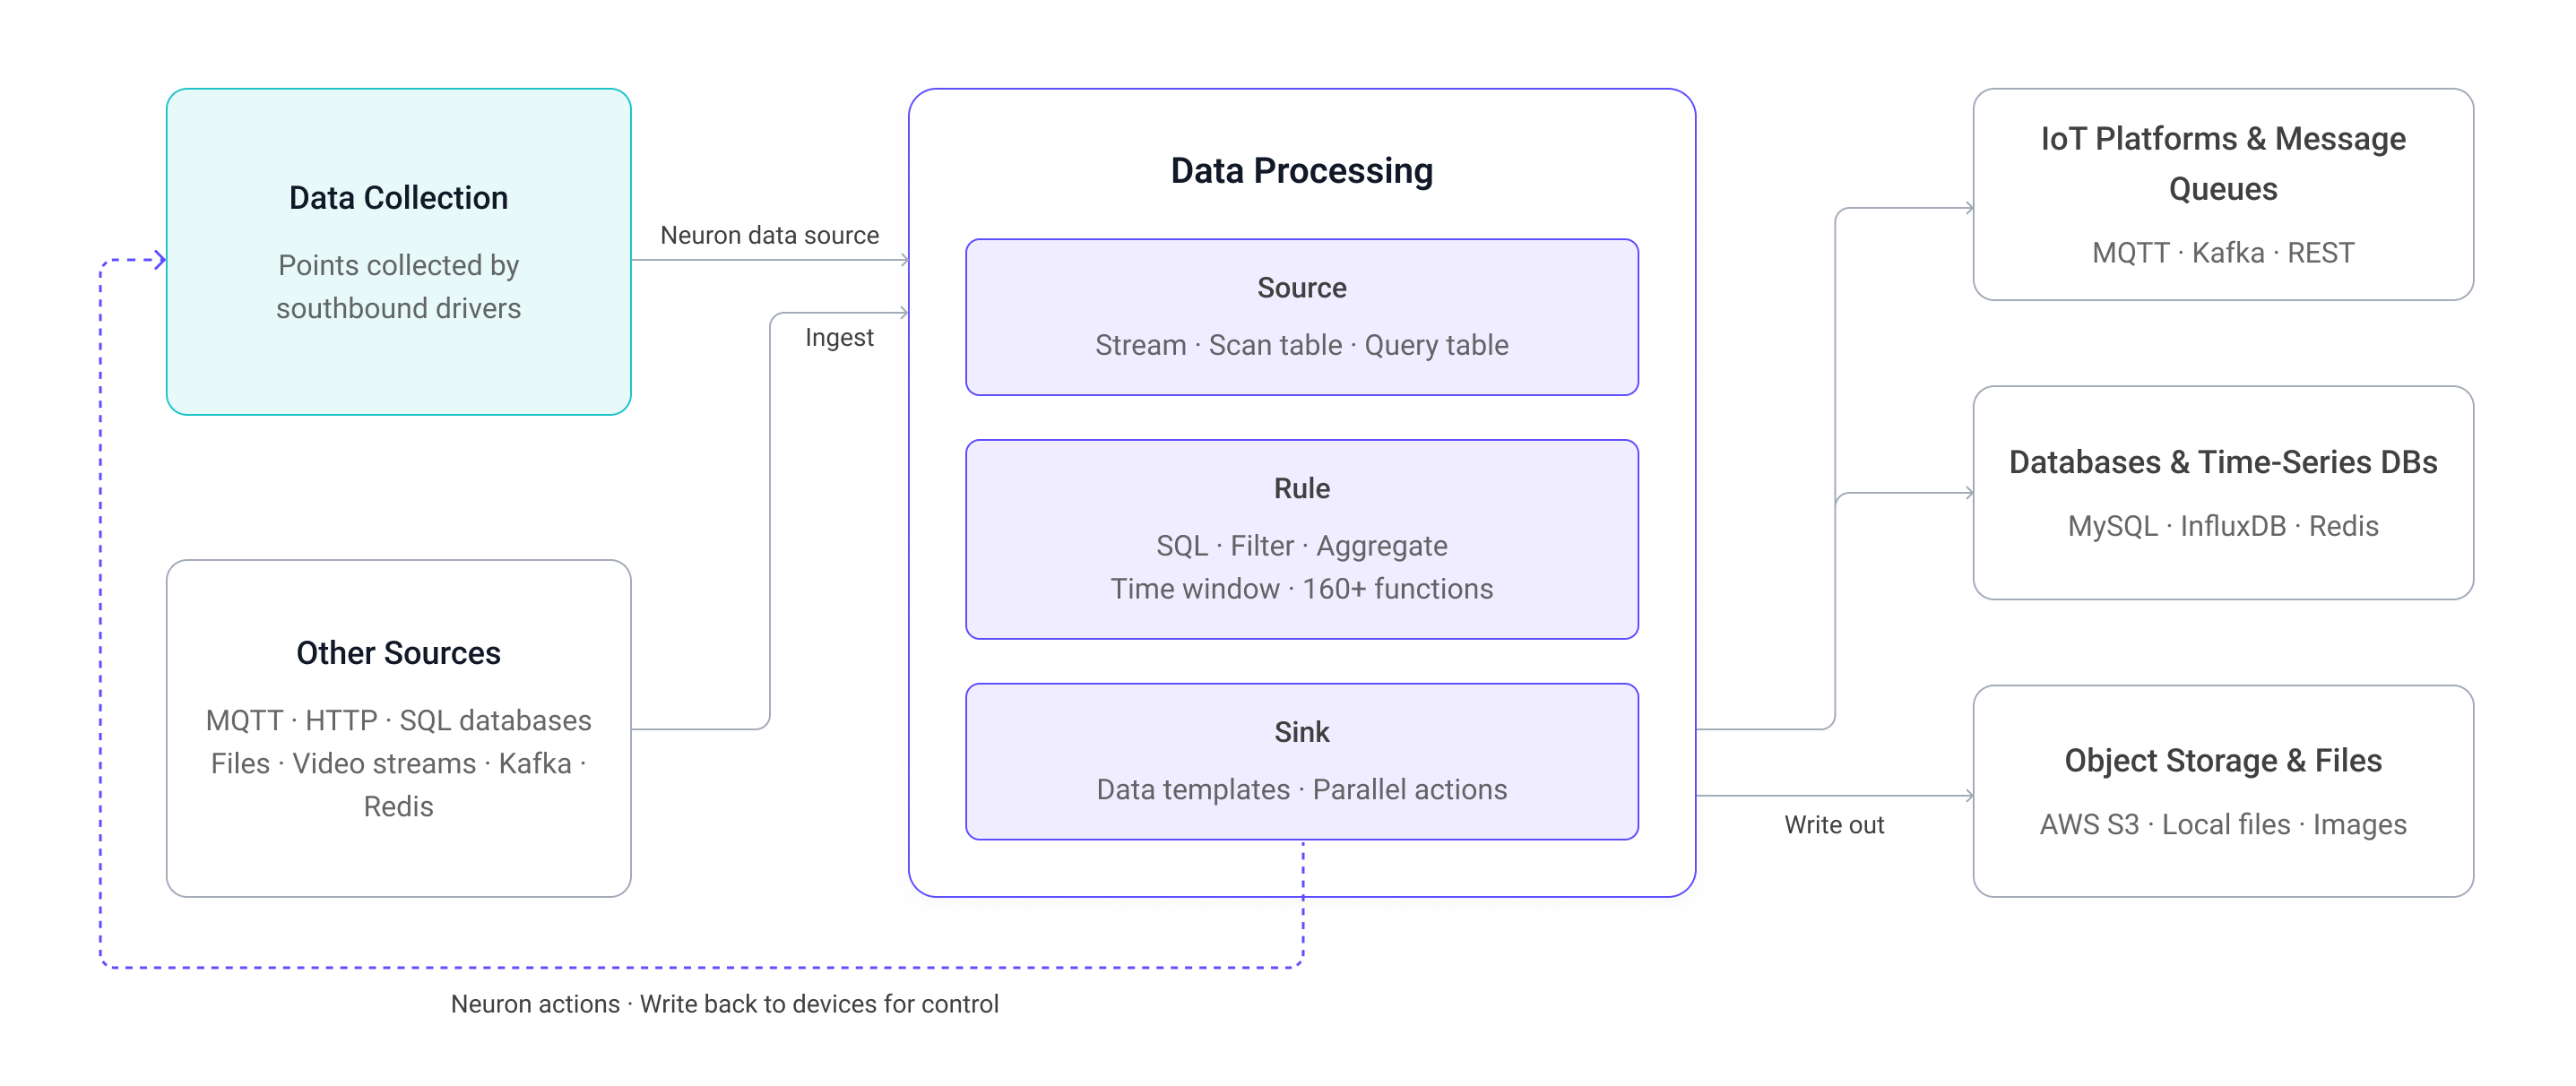
EMQX Neuron includes a stream processing engine that filters, converts, aggregates, and evaluates alarms before data leaves the edge.
When to use it
Southbound data can be published directly by a northbound application without passing through data processing. Process it through a rule first when:
- The polling rate far exceeds what the business needs. Polling every 100 ms catches transients, but a report only needs a per-minute average. Aggregating over a time window before publishing cuts volume by two orders of magnitude.
- Values barely move in steady state. During normal operation tag values are nearly constant. A conditional filter publishes only when a value moves beyond a threshold.
- Alarms need sub-second response. Keeping the decision at the edge avoids a cloud round trip and keeps working while the link is down.
- Units or field names need normalizing before publishing. Doing it once at the edge beats doing it in every downstream system.
Both paths can run side by side. For selection guidance, see Northbound Applications · Feed Analytics and Edge Computing.
Reading order
- Your First Rule: bring collected data in, transform it with one SQL statement, and publish to MQTT
- Source: define where data comes from, used as a stream or a table in rules
- Rules: write SQL, add actions, and debug
- Sink: where rule results go
Connecting to the collection module
Data processing and the collection module are linked in both directions. These two connectors are the ones used most:
| Direction | What to use | Notes |
|---|---|---|
| Collection → rules | Neuron source | The northbound Rules Engine Application feeds subscribed collection groups into the neuronStream stream. The application exists by default — just add a subscription. See Rules Engine Application |
| Rules → devices | Neuron sink | Rule results are written back to devices through southbound drivers, closing a collect → decide → control loop at the edge |
Sources
A source defines how to connect to an external system. Creating one only registers a logical definition; data flows only once a rule that references it starts. The same definition can be used in the FROM clause of many rules.
In a rule, a source is used either as a stream or a table: a stream triggers computation whenever data arrives; a table represents the current state of a stream for batch processing, and comes in scan and lookup forms.
Decoding is set with the format property, which supports json, binary, protobuf, and delimited, or custom for your own format.
Type | Purpose |
|---|---|
| Neuron | Tag data collected by the collection module |
| MQTT | Subscribe to an MQTT topic |
| HTTP Pull | Poll an HTTP service on a timer |
| HTTP Push | A built-in HTTP server that receives client pushes |
| Memory | Receive the output of a previous rule, forming a pipeline |
| SQL | Query MySQL, PostgreSQL, SQL Server, Oracle, or SQLite |
| File | Read file contents |
| Video | Pull a video stream |
| Simulator | Built-in simulated data for debugging rules |
| Redis | Read from Redis |
| CAN | Read from a CAN bus |
| Kafka | Consume a Kafka topic |
| WebSocket | Receive over WebSocket |
Sinks
A rule can have several actions, including more than one of the same type. Results can be reshaped by a data template before output; without one, the rule result is written as is.
Type | Purpose |
|---|---|
| MQTT | Publish to an external MQTT service |
| Neuron | Write back to devices |
| REST | Call an external HTTP API |
| Memory | Pass to the next rule, forming a pipeline |
| Log | Write to the log, normally for debugging only |
| SQL | Write to a relational database |
| InfluxDB V1 / V2 | Write to a time-series database |
| File | Write to a file |
| Kafka | Write to a Kafka topic |
| Redis | Write to Redis |
| AWS S3 | Upload to object storage |
| Image | Save as an image file |
| Nop | Discard output, for performance testing |
SQL capabilities
| Capability | Description | Learn more |
|---|---|---|
| Query and transform | Extract, convert, filter, sort, group, aggregate, plus LEFT / RIGHT / FULL / CROSS joins | Query language |
| Functions | 160+ covering math, strings, aggregation, hashing, date and time, JSON, arrays, objects, and analytics | Functions |
| Windows | Tumbling, hopping, sliding, and session time windows, plus count windows | Windows |
| Custom extensions | What SQL cannot express can be written in Python, C/C++, or JavaScript, or registered as an external REST service | Extensions |
How rules run
- A rule runs continuously once started, until stopped manually; it also stops on an error or when the instance exits.
- Rules are isolated from each other, so an error in one does not affect the others. They share the same hardware, and each rule can set an operator buffer to cap its processing rate.
- Rules can be chained into a pipeline through memory or MQTT source/sink pairs. See Rule Pipeline.
- Enable rule testing while creating a rule to see live whether the SQL, functions, and data template produce what you expect.
Configuration
The configuration page manages connectors (connection reuse), schemas for decoding formats such as Protobuf, and file management.